


Data Anonymization Services
Prepare your sensitive data for AI training, analytics, and controlled sharing. Get personal and confidential information processed according to your requirements, with custom replacement rules designed to preserve useful context and human-led QA review.
REQUEST PILOTTrusted by 200+ ML teams


Data and Sensitive Information We Process
Personal Identifiers (PII)
Names, email addresses, phone numbers, postal addresses, dates of birth, passport numbers, Social Security numbers, tax IDs, and driver's license numbers.
Text and Conversational Data
Customer service emails, chat histories, call transcripts, documents, and other text records containing personal or confidential information.
Financial and Account Information
Payment card numbers, CVV/CVC codes, bank account details, IBANs, account IDs, usernames, passwords, API keys, and authentication codes.
Numerical and Continuous Attributes
Exact ages, income figures, dates, geographic coordinates, and other numerical attributes that may contribute to identifying individuals.
Visual and Biometric Data
Faces, license plates, distinctive tattoos, and other identifying features in images or video footage, where visual anonymization is included in the agreed project scope.
Sensitive Data Holding Up Your AI Project?
Pick Your Data Anonymization Use Case
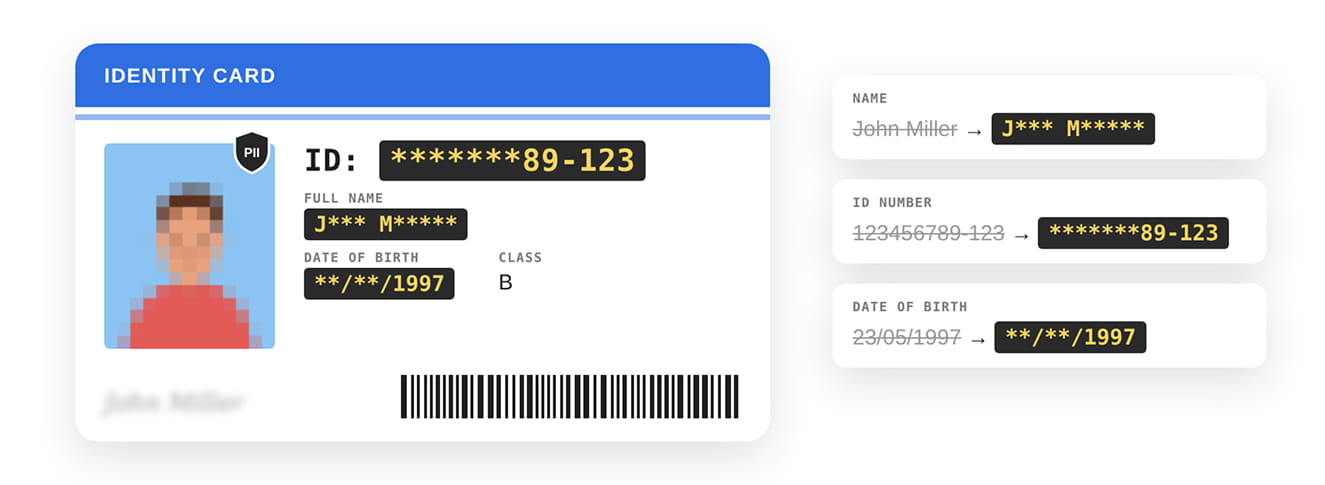
Exact ages, income figures, dates, geographic coordinates, and other numerical attributes that may contribute to identifying individuals.
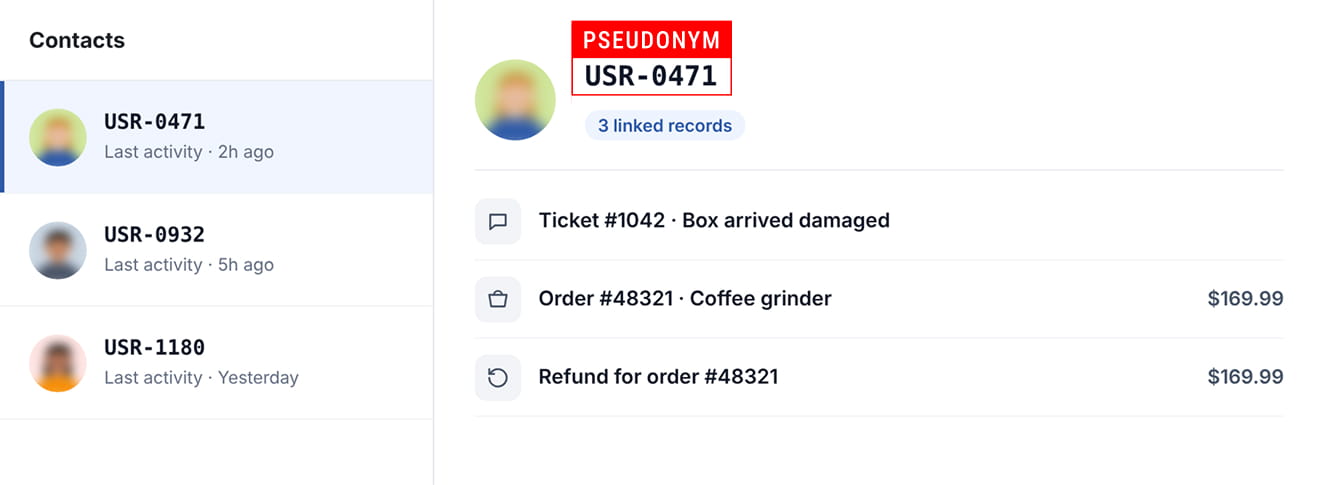
Replace direct identifiers with consistent artificial IDs or pseudonyms to preserve relationships within your dataset. Where separately held information can reconnect records to individuals, the data remains personal data.
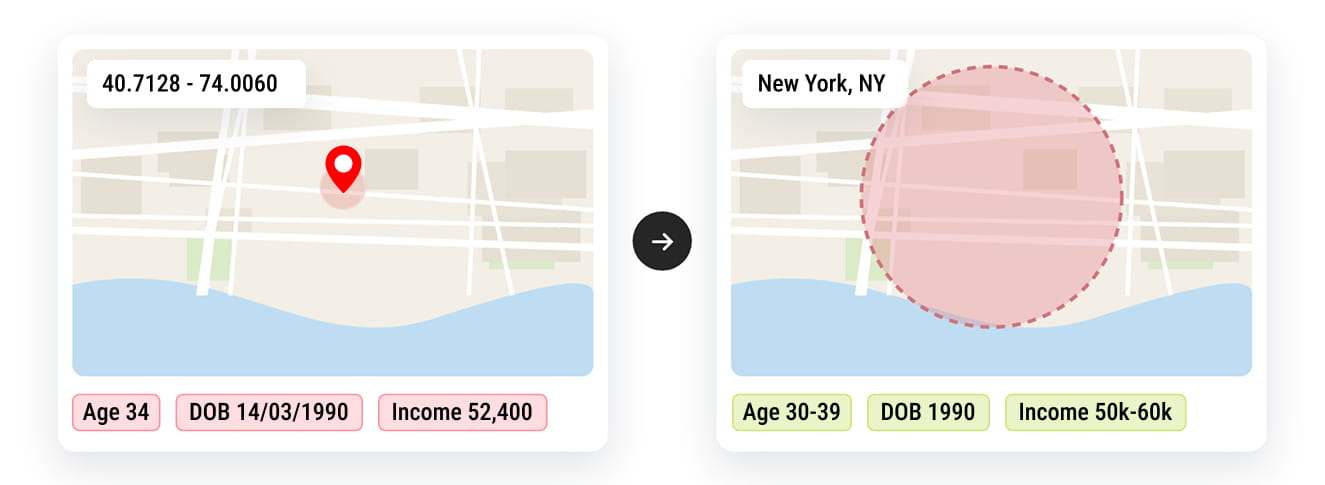
Reduce the precision of sensitive attributes, such as converting exact ages into age ranges or geographic coordinates into broader locations.
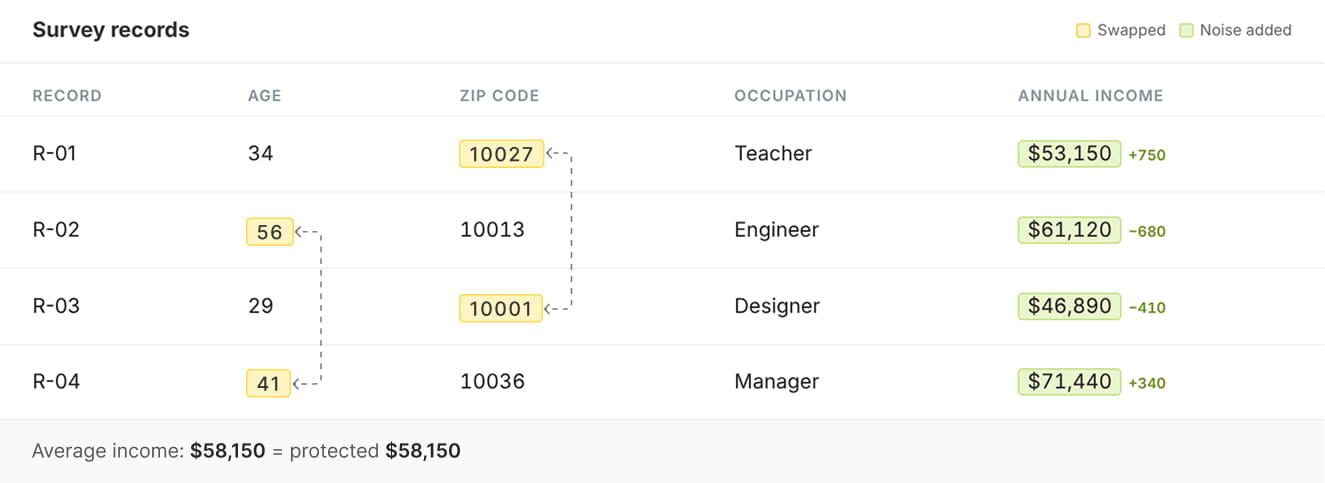
Rearrange selected values or add controlled noise to numerical data to reduce identification risks while retaining useful statistical characteristics.
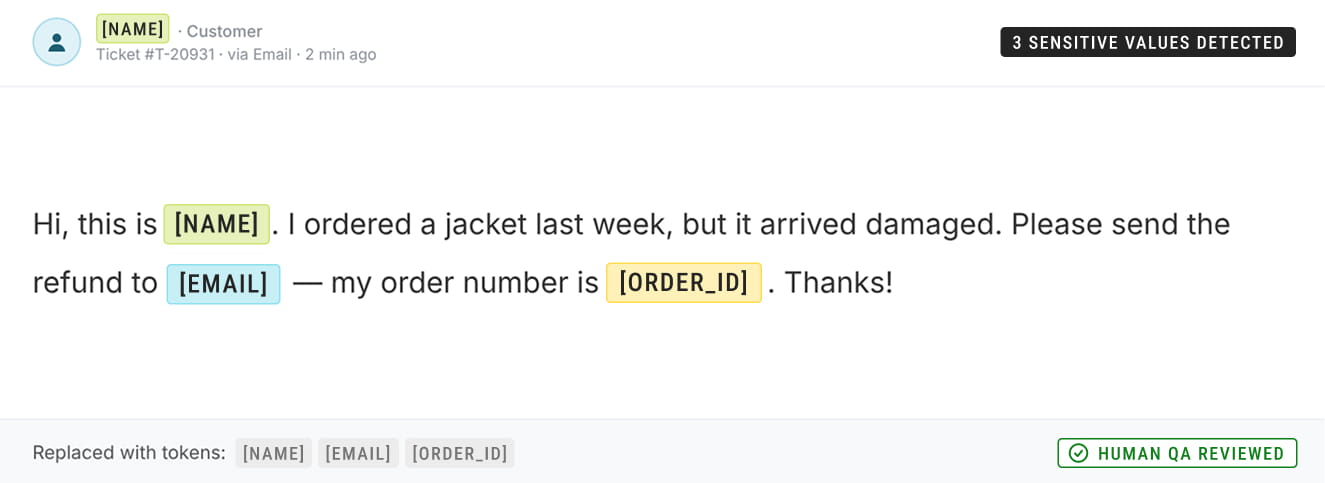
Replace selected sensitive values with placeholders such as [NAME], [EMAIL], and [ORDER_ID], keeping the surrounding text understandable for downstream use. Our preprocessing workflow uses token-replacement functionality described in U.S. Patent No. 11,823,031, with project-specific rules and human QA review.
Exact ages, income figures, dates, geographic coordinates, and other numerical attributes that may contribute to identifying individuals.
Replace direct identifiers with consistent artificial IDs or pseudonyms to preserve relationships within your dataset. Where separately held information can reconnect records to individuals, the data remains personal data.
Reduce the precision of sensitive attributes, such as converting exact ages into age ranges or geographic coordinates into broader locations.
Rearrange selected values or add controlled noise to numerical data to reduce identification risks while retaining useful statistical characteristics.
Replace selected sensitive values with placeholders such as [NAME], [EMAIL], and [ORDER_ID], keeping the surrounding text understandable for downstream use. Our preprocessing workflow uses token-replacement functionality described in U.S. Patent No. 11,823,031, with project-specific rules and human QA review.
Our Data Anonymization Process and QA
Data Assessment and Planning
We review your dataset, requirements, and intended use to agree on processing scope, sensitive entities, replacement rules, quality checks, and the information that must remain intact.
Data Processing
Our annotation team identifies and replaces sensitive information according to the agreed guidelines, applying custom anonymization rules across your dataset.
Anonymization QA
Our QA specialists check for missed sensitive entities, incorrect replacements, and inconsistencies. Identified issues are corrected before delivery.
Processed Dataset Delivery
Receive your processed dataset in the agreed format, ready for your team to validate against its intended use and acceptance criteria.


How We Protect Your Source Data
ISO 27001-Certified Security
Our information security management system supports secure handling of sensitive datasets through established security controls and risk management practices.
GDPR, CCPA, and HIPAA
We align project-specific data handling requirements with applicable privacy regulations, helping your team address relevant security, confidentiality, and data protection obligations.
Patent No. 11,823,031
The patent documents a technical approach to replacing sensitive information with predefined tokens, helping protect identifying details while preserving valuable context for downstream AI processing and analysis.
Client Data Ownership and Secure Access
You retain ownership of your data. Role-based access controls restrict access to authorized personnel, while data is handled according to agreed security requirements and workflows, including AWS S3 where applicable.
ZERO data-leak incidents since the inception of Label Your Data.
How We Deliver Data Anonymization in Practice
ENTERPRISE CYBERSECURITY
Sensitive Data Replacement for a Cybersecurity Software Provider
We supported a cybersecurity software provider with a data anonymization pilot, replacing personal names and addresses with synthetic alternatives. Our team followed client-specific requirements to protect sensitive information while preserving the original text structure.


CUSTOMER SUPPORT DATA
Large-Scale Customer Email Anonymization
Our team anonymized 27,500 customer emails stored in CSV files, replacing sensitive information with predefined placeholders according to client-specific guidelines.
The project was completed in just 2 weeks, with a dedicated team of 6 annotators and 2 QA specialists managing data processing and quality assurance.
Protect Sensitive Information Without Losing
the Value of Your Data
Reviews
What Our Clients Say


Label Your Data has successfully collected data from public sources, annotated missing skeletons, and validated pre-annotations for almost 15,000 images. Although their instructions are sometimes unclear, the team has received praise for their flexibility and speed. They also communicate via email.

Jack Prescott
Software Engineer, Nex
Label Your Data has delivered high-quality data labels, which have received positive client feedback. Their team produces outputs on time and solves challenges without upselling. They also communicate effectively through virtual meetings.

Ben Niehaus
CTO, SpexAI GmbH
Label Your Data's support has been crucial in developing the client's computer vision perception algorithms. They lead a simple and effective collaboration by responding quickly to concerns and questions and delivering everything on time.

Piotr Swierczynski
Director of Engineering, NODAR
Label Your Data provided the client with high-quality annotations and added to the number of annotations in the client's portfolio. The team was consistently available for questions or updates that needed to be added to the data set. The client was impressed with the team's communication skills.

Josha Bharadwa
Software Architect, Searidge Technologies
Label Your Data continues to work diligently for the client. They consistently provide training data for different document types and languages. Furthermore, they are excellent communicators and collaborators, and their ability to serve high-quality services is outstanding.

Luca van Skyhawk
VP of Customer Success, Hypatos GmbH
After engaging with Label Your Data, the client has seen a reduction in error rate and success with model accuracy running on production. The team delivered on time and was communicative in their approach. The client was impressed with the steps Label Your Data took to ensure accurate QA testing.

Radouane Kaddari
Machine Learning Engineer, Peter Park
Why AI Teams Choose Label Your Data

Data Annotation for Complex Environments
Rely on consistent, high-quality output for complex datasets, detailed taxonomies, and edge cases.

Structured Quality from Pilot to Production
Get quality engineered into every step through onboarding, evolving guidelines, QA, and continuous feedback.

Flexible and Scalable Operations
Adjust team capacity, project size, and delivery model as you scale, with no setup fees or long-term lock-ins.

An Integrated Delivery Partner
Align on goals, workflows, and expectations with a team that integrates into your process from day one.

Projects Led by Annotation Experts
Work with former annotators who understand annotation complexity, quality standards, and high-volume delivery.
Request a pilot
Tell us more about your project and data

Thank you for contacting us!
We'll get back to you shortly


After running pilots with several annotation providers, Label Your Data delivered the strongest results by a clear margin, standing out on turnaround time, annotation quality, and the responsiveness of their feedback loops.

Maxime Debarbat
Senior ML Engineer (GenAI)
Trusted by ML Professionals


FAQs
What is data anonymization?

Data anonymization is the process of transforming personal information so individuals can no longer be identified. It can involve removing, replacing, or generalizing sensitive details while preserving useful information for analytics, research, or AI development.
What is the difference between data masking and data anonymization?
Data masking hides or replaces specific values, such as names, email addresses, or account numbers. Data anonymization goes further by ensuring individuals cannot reasonably be identified from the resulting information. Masking alone does not necessarily make a dataset anonymous.
What types of data can Label Your Data anonymize?
We process sensitive text in customer emails, chat histories, call transcripts, documents, and structured datasets. Your project scope defines the supported file formats, sensitive information categories, and replacement rules, including any requirements for image, video, or file metadata processing.
How do you anonymize your data?
Data anonymization typically involves identifying sensitive information, selecting appropriate transformation methods, applying replacement rules, and reviewing the results. At Label Your Data, we manage these steps according to project-specific guidelines, with dedicated processing and QA teams.
Can anonymized data be used for AI training?
Yes, appropriately prepared datasets can support AI training, testing, and analytics. The key is to protect sensitive information while retaining the context and relationships required for the intended task. The resulting dataset should be evaluated for both usefulness and identification risks.
How do you ensure data anonymization quality?
Our managed workflow includes dedicated QA specialists who review processed data for missed sensitive entities, incorrect replacements, and inconsistencies with project guidelines. Identified issues are corrected before delivery.
How much do data anonymization services cost?
Pricing depends on your data volume, complexity, sensitive information categories, replacement rules, and QA requirements. We assess your dataset to provide a project-specific estimate. You can also explore our data annotation pricing page and cost calculator for general annotation estimates; anonymization pricing is confirmed separately.
Can we test your data anonymization services before starting a large project?
Yes. Start with a no-cost pilot on a representative sample to review how sensitive information is handled and whether the output remains useful for your intended task. The pilot helps confirm replacement rules, acceptance criteria, and the estimated cost and timeline for production.
What are the best data anonymization tools?
The best data anonymization tools depend on your data formats, volume, sensitive information categories, and privacy requirements. Automated tools can help detect and transform sensitive information, while managed data anonymization services provide human processing, custom guidelines, and quality assurance for complex datasets.